Project Knowledge Graph
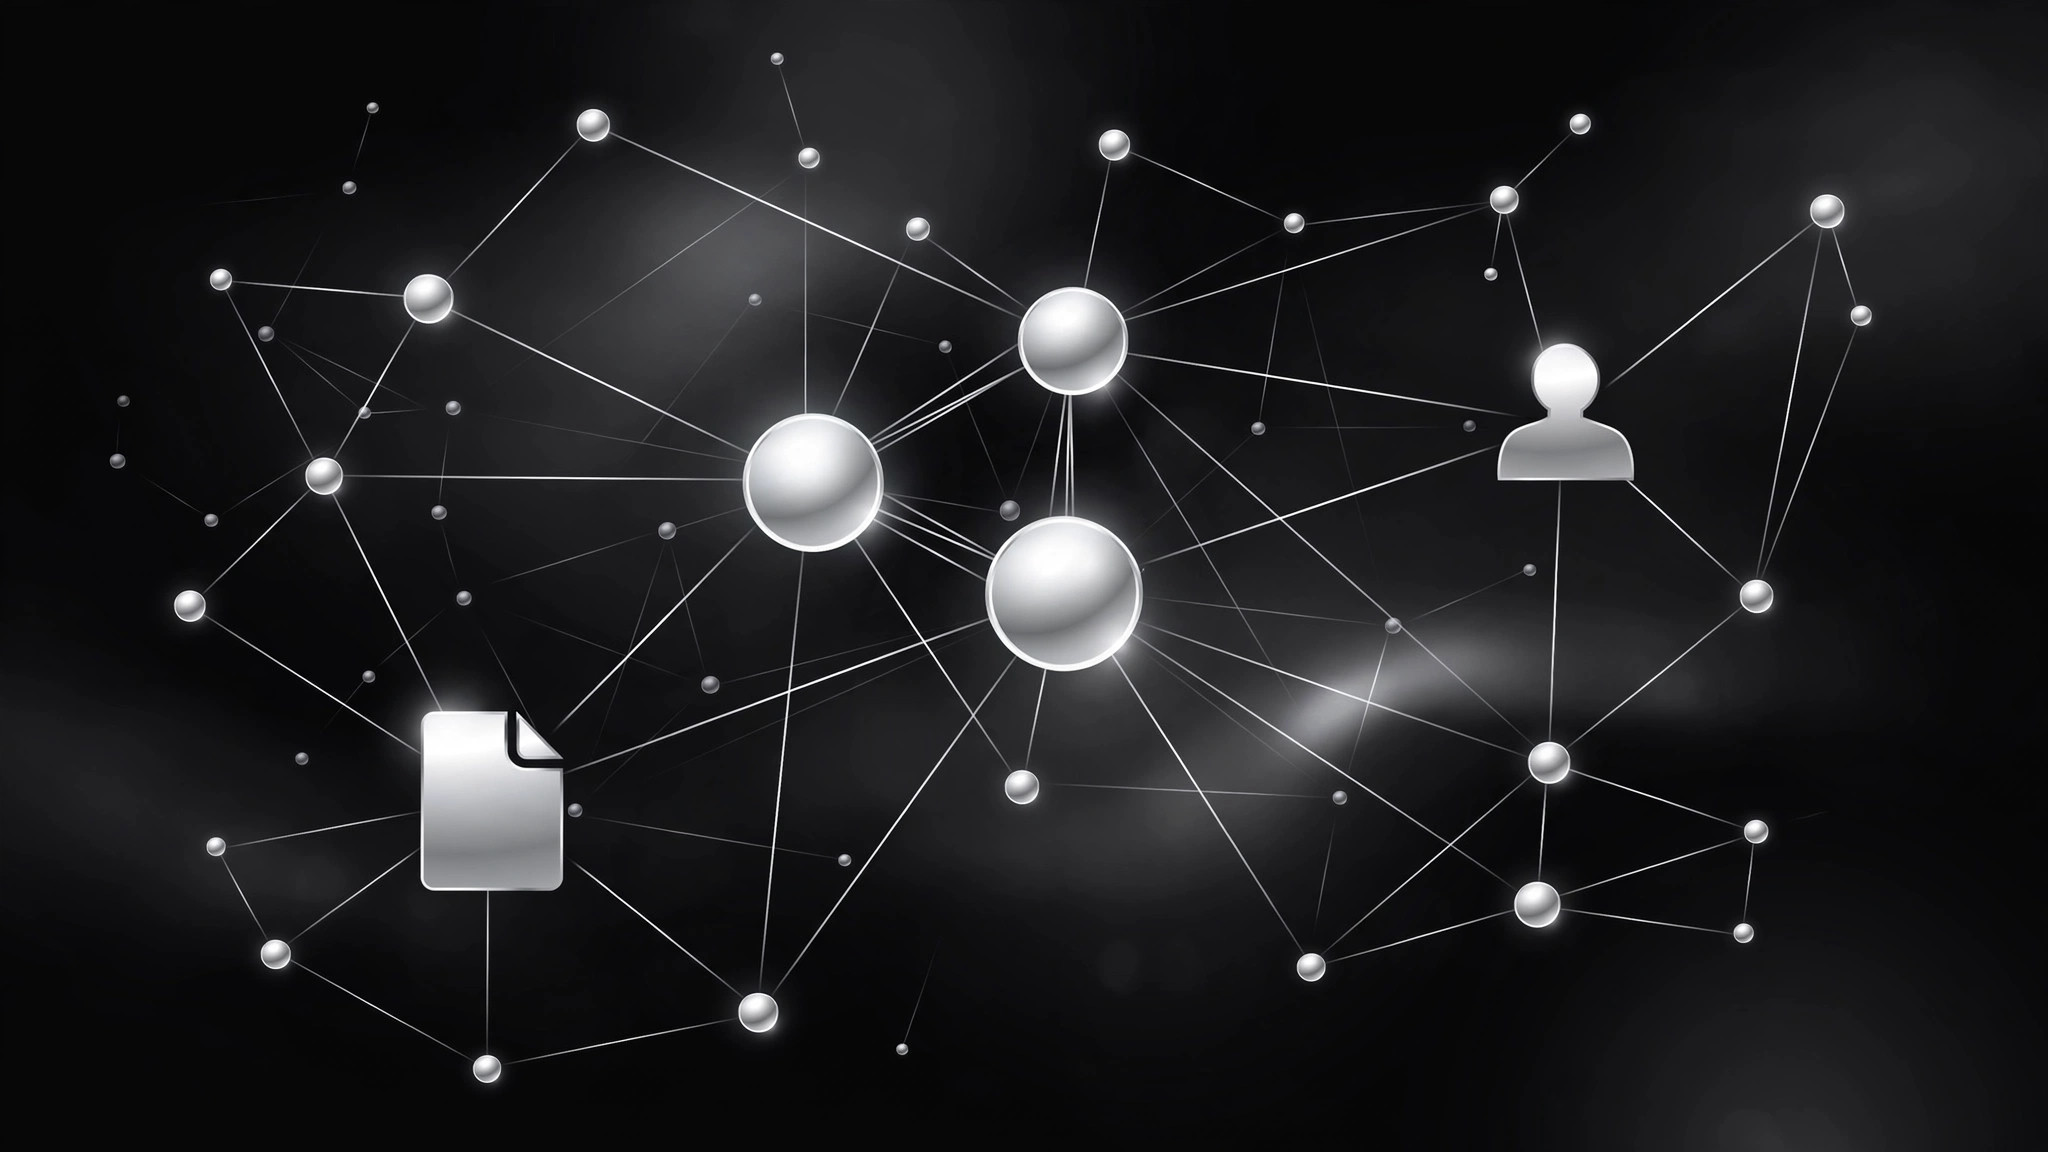
Wie das Projekt zusammenhängt — auf einer Karte.
Verwandelt Ihre KI in einen Knowledge-Graph-Designer für ein Projekt — bildet die Menschen, Entscheidungen, Dokumente und Dateien des Projekts als Knoten und Beziehungen ab, sodass Neue auf einen Blick sehen, wie die Arbeit zusammenhängt, statt sich durch Ordner zu wühlen.
In 3 Schritten installieren
Keine Anmeldung. Keine CLI-Tools. Wählen Sie Ihre AI, kopieren Sie eine Zeile und fügen Sie sie ein.
Lieber selbst machen? Kaufen Sie den Skill ($4.99), laden Sie die ZIP-Datei aus Ihrer Kaufbestätigung herunter, entpacken Sie sie in das oben angezeigte Verzeichnis und starten Sie Ihre AI-Sitzung neu — gleiches Ergebnis. Haben Sie ihn schon gekauft? Ihr AI-Assistent kann ihn für Sie herunterladen.
Was ist enthalten
Eine SKILL.md (die Anleitung) + eine Startvorlage. Eine Vorschau:
Project Knowledge Graph
When to use
- A new joiner asks "how does this project fit together?" and the honest answer is a tour of five folders and three chat histories
- Decisions live in people's heads or scattered threads, and the same question gets re-decided every few months
- Your project has more than a dozen documents and nobody can say which ones are current
- You need to find the blast radius of a change: what breaks if this requirement, vendor, or person changes
- Handover is coming and the knowledge can't walk out the door with one person
Workflow
- Set the boundary (input: project → output: scope statement)
Name the project and draw its boundary in one paragraph: what's in (the product, the team, the docs, the decisions) and what's out (adjacent projects, company-wide policies). A graph without a boundary becomes a map of everything, which is a map of nothing. List the sources you'll draw from: the docs folder, the decision log or meeting notes, the task tracker, the repo, the chat channels. If a source is off-limits, say so now — a graph that silently omits the place where decisions actually happen teaches false confidence. - Define the entity types (input: scope → output: entity schema)
Fix a small set of node types — five to seven, no more: Person, Decision, Document, Task, Component (a part of the product), Requirement, and External (a vendor, client, or dependency). Every node gets the same fields: name, one-line description, owner, date last verified, and source link. Every node also gets a status: current, superseded, or draft. Define the relationship types too: decides, depends on, documents, owns, blocks, supersedes. A small fixed vocabulary beats a free-for-all — if two people can describe the same link differently, the graph can't be queried or trusted. - Extract the nodes (input: sources → output: node list)
Go through the sources and list every entity that matters: every decision with its date and decider, every document with its status, every component with its owner, every person with their role on this project. Prefer extraction from real sources over recall — quote the doc, link the thread, cite the meeting date. Mark anything uncertain as draft and note what's missing ("decision date unknown — confirm with {name}"). A graph with honest gaps is useful; a graph that presents guesses as facts is a trap. Expect the first pass to surface duplicates and contradictions — two docs describing the same decision differently is a finding, not a failure. - Draw the relationships (input: node list → output: connected graph)
Connect the nodes with the fixed relationship vocabulary: this Decision was made by that Person, this Document documents that Decision, this Task is blocked by that External dependency, this Document supersedes that Document. Then prune: remove nodes with no relationships (if nothing connects to it, it probably doesn't belong), and collapse duplicates into one node with both sources cited. Check the shape: a healthy project graph has a few well-connected hubs (core decisions, core components) and no orphan clusters. An orphan cluster usually means a part of the project nobody has connected to the whole — investigate it, don't delete it. - Publish and maintain (input: connected graph → output: living graph + update routine)
Publish the graph where the team already works — a wiki page, a shared doc, or a graph tool the team already uses — with a one-paragraph "how to read this" guide and a visible "last verified" date. Set the update routine: every decision meeting adds or updates nodes the same day; every month, one person checks for superseded docs and stale links. The graph dies the week maintenance stops, so the routine matters more than the first draft. When a new joiner uses it, ask them what they couldn't find — their confusion is the graph's next fix.
Vorschau der Startvorlage
Project Knowledge Graph — Build Template
A map of how the project fits together. Scope first, sources always, honest gaps.
Scope statement
- Project: {name}
- In: {product, team, docs, decisions — what the graph covers}
- Out: {adjacent projects, company-wide policies — what it does not cover}
- Sources used: {docs folder / decision log / meeting notes / task tracker / repo / chat channels}
- Sources excluded: {off-limits sources — named, not silently omitted}
Entity schema (fixed — 5–7 node types)
Relationship vocabulary (fixed — add types deliberately, with a definition):
Node list (extract from real sources — quote the doc, link the thread)
Das Skill-Paket selbst (SKILL.md + Vorlage) ist auf Englisch verfasst.