Title Behind Subject
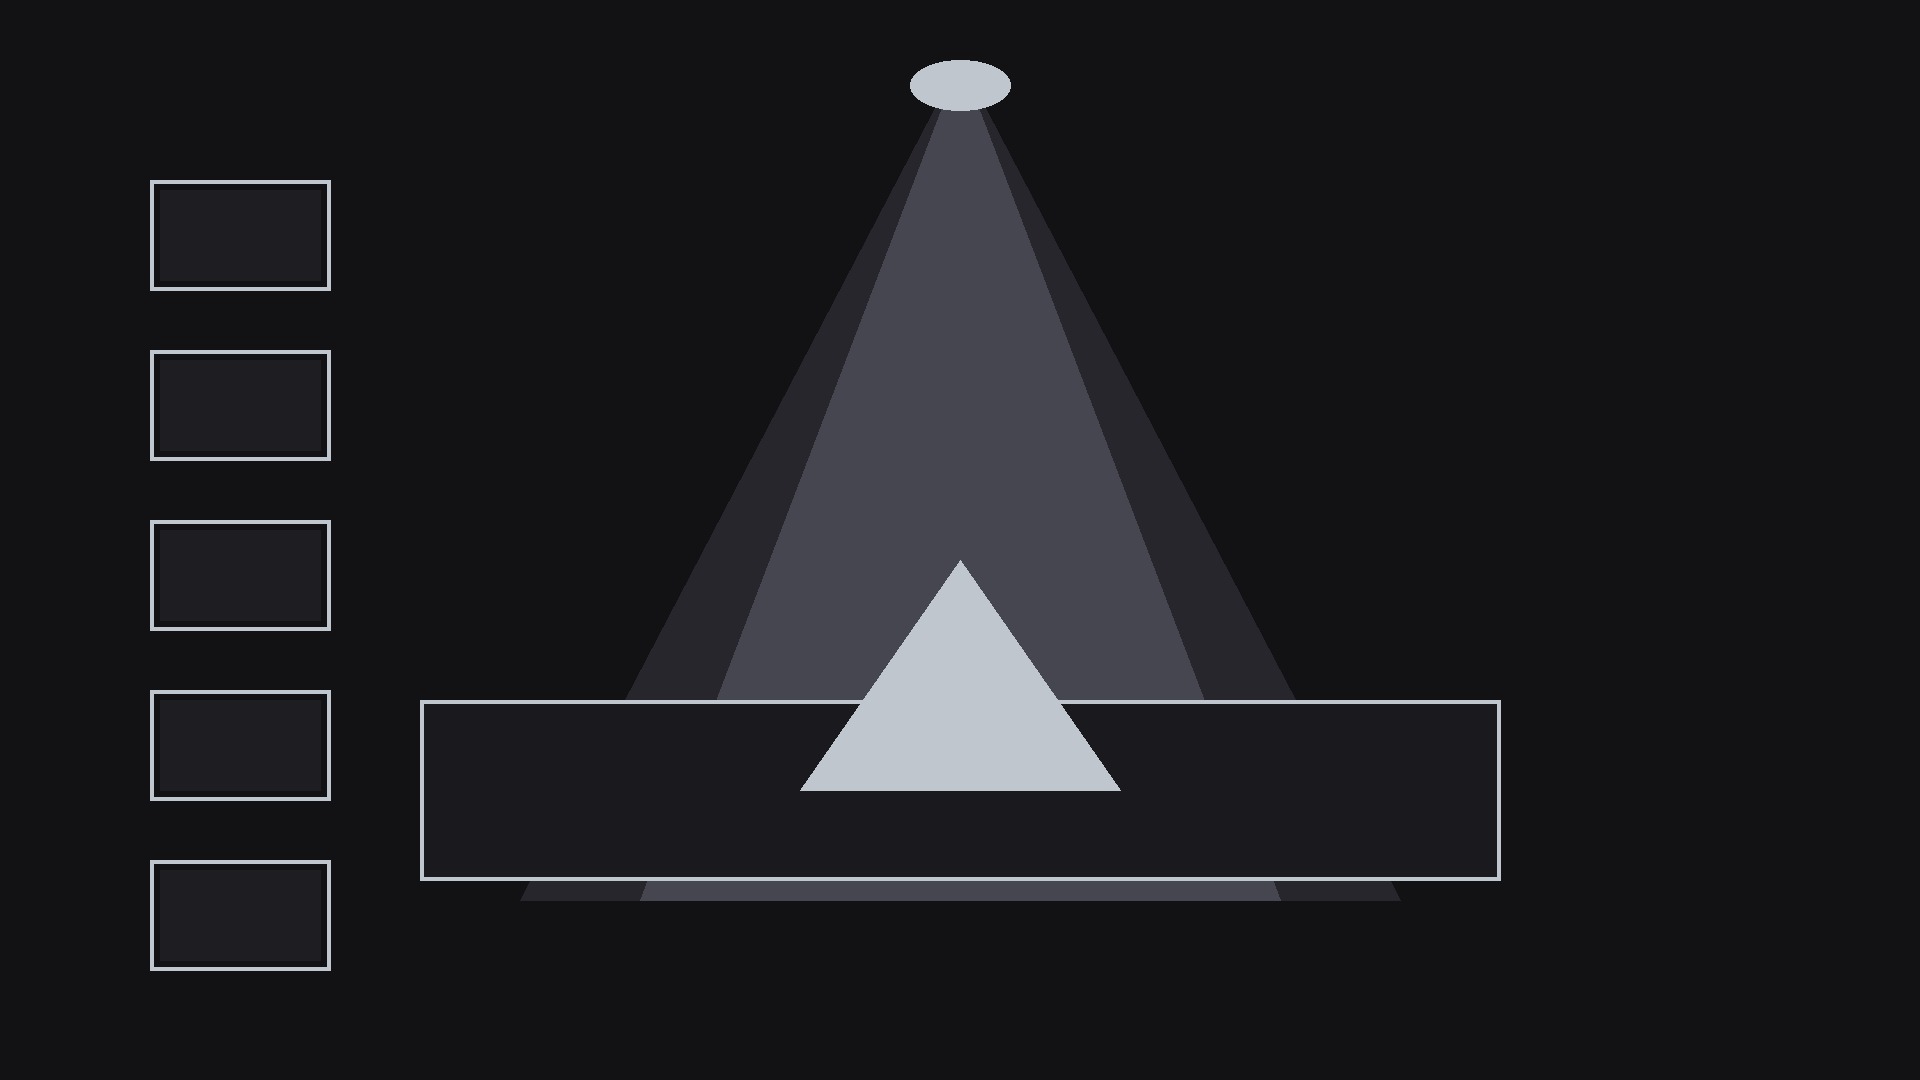
Votre titre vit dans le plan — derrière le sujet, pas par-dessus.
Place votre titre vidéo derrière la personne ou l’objet du plan pour qu’il se lise comme une partie de la scène. Couvre le masque du sujet, le sandwich en trois couches, le minutage du titre et la finition d’ombre qui vend la profondeur.
Installez-la en 3 étapes
Sans inscription. Sans outils en ligne de commande. Choisissez votre IA, copiez une ligne, collez-la.
Vous préférez le faire vous-même ? Achetez la compétence ($4.99), téléchargez le ZIP depuis votre confirmation d'achat, décompressez-le dans le répertoire indiqué ci-dessus, redémarrez votre session IA — même résultat. Vous l'avez déjà achetée ? Votre assistant IA peut la télécharger pour vous.
Contenu du pack
Un fichier SKILL.md (le guide pratique) + un modèle de départ. Aperçu :
Title Behind Subject
When to use
- Your video opens on a person talking to camera and you want the title to feel like it lives inside the shot, not on top of it
- A product shot, a landscape, or a workspace deserves a title that sits in the scene's depth rather than floating over it
- You are making a channel intro, a course lesson opener, or a short-form hook where the first 2 seconds decide whether anyone keeps watching
- The subject is clearly separated from the background — a person against a wall, a product on a table, a building against sky — so a clean cutout is possible
- You want one strong title moment per video, not text competing with the subject for the whole runtime
Workflow
- Pick the shot and the title (input: raw clip + title text → output: locked shot and title line)
Choose a shot where the subject stays roughly in one place for at least 2 seconds and does not cross the area where the title will sit. A talking-head shot with the head in the upper third works; a subject walking across the frame does not. Write the title as 1–5 words — long titles cannot sit behind a subject without getting swallowed. Set the title in a heavy weight (700–900) at a size that spans 60–90% of frame width; thin fonts disappear behind the subject and defeat the effect. Decide the title's resting position now: centered behind the subject's torso, or lower-third behind the subject's shoulder. Lock it before you animate anything. - Cut out the subject (input: locked shot → output: clean subject mask)
Duplicate the video layer and isolate the subject on the top layer. In most editors this is a mask, a rotoscope brush, or an auto subject-select tool followed by manual cleanup. Trace the subject's outline with a 2–4 px feather so the edge does not buzz against the text. The mask only needs to be accurate where the title passes behind the subject — spend your cleanup time on the head, shoulders, and any arm that crosses the title zone, and leave the rest rough. If the subject moves, keyframe the mask every 4–6 frames on fast motion, every 10–12 on slow motion; the eye forgives a slightly soft mask edge but never forgives text bleeding over a face. Export a quick preview of the mask alone (subject white, background black) and check for holes — a hole in the torso lets title text leak through the body. - Stack the layers (input: mask + title → output: three-layer sandwich)
Order from bottom to top: (1) original video, (2) title text, (3) masked subject cutout. The title now sits between the scene and the subject, which is the entire trick. Nudge the title so 15–30% of it is hidden behind the subject — enough overlap to sell depth, not so much that the words become unreadable. If the title crosses the subject's face, move the title down or shrink it; text behind a face reads as a mistake, text behind a torso reads as design. Keep the title on screen for 1.5–3 seconds total: long enough to read twice, short enough to stay a moment rather than a watermark. - Animate the title (input: stacked layers → output: timed title move)
Animate the title, not the subject. The classic move: title slides up from below the frame over 0.4–0.6 s with an ease-out curve, holds still for 1.0–1.5 s, then either fades out over 0.3 s or slides on through and exits the top. Add a subtle scale from 96% to 100% during the entrance so the title feels like it settles rather than slams in. If the subject is walking toward camera, add a matching slow zoom (100% → 104%) to the whole sandwich so the title rides the shot's energy. Never animate the title sideways across the subject's face — lateral moves drag the eye across the person instead of to the words. Keyframe timing: entrance starts 0.2 s after the shot cuts in, so the viewer lands on the subject first, then discovers the title. - Finish with light and shadow (input: animated sandwich → output: final title moment)
Sell the depth illusion. Add a soft drop shadow to the title (opacity 25–35%, blur 8–12 px, offset 4–6 px down) so it feels like it sits on the background wall rather than on the lens. If the scene has a dominant light direction, match the shadow to it. Drop the title's opacity to 90–95% if the background is bright — full-white text on a bright wall looks pasted; slightly transparent text looks printed. Check the final frame on a phone screen at arm's length: if you can read the title in under a second and the subject still owns the frame, it is done. If either fails, adjust size and overlap before touching anything else.
Aperçu du modèle
Title Behind Subject — Build Template
One title moment per scene. Fill this in before cutting any mask.
Shot: {clip name / timecode}
Subject: {person / product / building} | Subject position: {center / left / right} | Subject movement: {still / leaning / walking toward camera}
Title text (1–5 words): {TITLE HERE}
Font: {heavy weight 700–900} | Size: {60–90% of frame width} | Resting position: {centered behind torso / lower third behind shoulder}
Mask plan
Tool: {mask / rotoscope / auto subject-select + cleanup} Feather: {2–4 px, or 4–6 px for fine hair} Keyframe every: {4–6 frames fast motion / 10–12 frames slow motion}
Le pack de compétence lui-même (SKILL.md + modèle) est rédigé en anglais.