AI Crawler Readiness Audit
Ist Ihre Website bereit für KI-Crawler? Prüfen und beheben
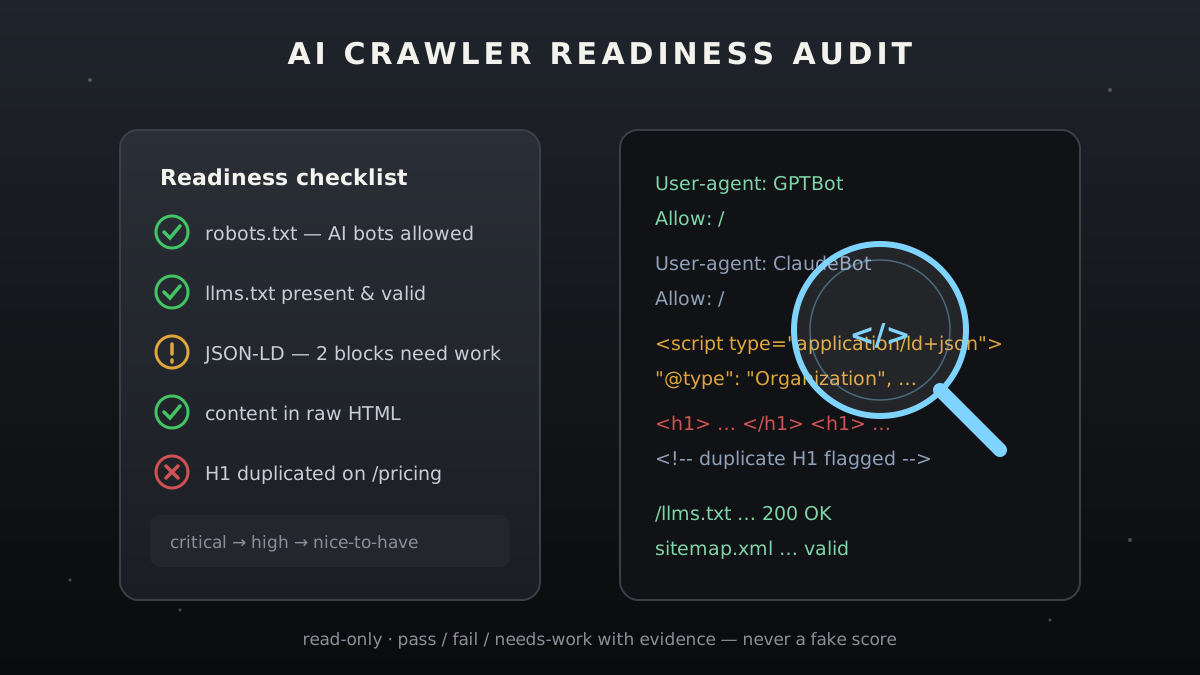
Ein rein lesender technischer Audit der KI-Crawler-Bereitschaft Ihrer Website: robots.txt-Regeln für GPTBot/ClaudeBot/PerplexityBot, llms.txt-Vorhandensein und -Qualität, JSON-LD-Validierung, Roh-HTML-Render-Checks und Content-Struktur. Sie erhalten eine priorisierte Fix-Checkliste — kritisch, hoch, nice-to-have — jeweils mit exakter Datei, zitiertem Beleg und konkretem Fix. Ändert nichts, kein Fake-Score.
In 3 Schritten installieren
Keine Anmeldung. Keine CLI-Tools. Wählen Sie Ihre AI, kopieren Sie eine Zeile und fügen Sie sie ein.
Lieber selbst machen? Kaufen Sie den Skill ($4.99), laden Sie die ZIP-Datei aus Ihrer Kaufbestätigung herunter, entpacken Sie sie in das oben angezeigte Verzeichnis und starten Sie Ihre AI-Sitzung neu — gleiches Ergebnis. Haben Sie ihn schon gekauft? Ihr AI-Assistent kann ihn für Sie herunterladen.
Was ist enthalten
Eine SKILL.md (die Anleitung) + eine Startvorlage. Eine Vorschau:
AI Crawler Readiness Audit
The facts this skill runs on (verified 2026-11-03)
- AI crawlers are bots, and bots read robots.txt. GPTBot, ClaudeBot, PerplexityBot and similar crawlers publish user-agent strings and, like respectable bots, honor robots.txt. If your robots.txt disallows them, the AI pipelines that respect it will skip your site. The audit starts here because a single disallow line can silently exclude you everywhere.
- llms.txt is a convention, not a standard. It's a Markdown file at
/llms.txtthat summarizes your site for AI assistants — what you do, where the key pages are. No standards body ratified it; adoption is voluntary and uneven. Having a good one helps the assistants that look for it; not having one isn't a penalty, just a missed opportunity. - Structured data is machine-readable trust. JSON-LD blocks (Organization, Product, FAQPage, Article, BreadcrumbList) let crawlers parse facts without guessing from prose. Valid structured data doesn't guarantee AI citations, but pages without it are harder for machines to quote accurately.
- If it needs JavaScript to exist, some crawlers won't see it. Simpler crawlers fetch raw HTML and never run your JS framework. The audit checks whether your key content — headlines, product facts, prices, FAQs — is present in the raw HTML. Server-rendered HTML is the safe baseline; client-only rendering is the most common readiness failure.
- This audit is read-only. It fetches public files (robots.txt, llms.txt, sitemap.xml, page HTML) and inspects them. It never logs in, never submits forms, never modifies anything, and never probes for vulnerabilities. Findings are pass / fail / needs-work with evidence, never a fabricated "readiness score."
When to use
- You want AI assistants to accurately describe and cite your site, and want to know what's technically blocking that today.
- You've published an llms.txt (or haven't) and want to know if it's well-formed and discoverable.
- Your content is JS-rendered and you suspect AI crawlers see a blank page.
- Before a launch or relaunch: a pre-flight check that the machine-readable layer is correct from day one.
Safety rules (non-negotiable)
Vorschau der Startvorlage
AI Crawler Readiness Audit — Job Report
One report per site per run. Fill every field — "n/a" is an answer, a blank is not.
Target
- Domain:
- Pages audited:
- Run date:
- Permission (own site / owner-requested):
1. Crawl surface
- robots.txt fetched:
- AI bots allowed: GPTBot / ClaudeBot / PerplexityBot /
*— - AI bots disallowed:
- Sitemap referenced & valid:
- Accidentally disallowed sections:
2. Machine-readable files
3. Structured data (per key page)
4. Render check (raw HTML, no JS)
5. Content structure
- One H1 per page:
- Descriptive titles (<~60 chars):
- Meta descriptions:
- FAQ as real Q&A:
Das Skill-Paket selbst (SKILL.md + Vorlage) ist auf Englisch verfasst.
FAQ
Does this skill change anything on my website?
No. It is strictly read-only: it fetches public files (robots.txt, llms.txt, sitemap, page HTML) and inspects them. Every finding comes with the exact evidence and the concrete fix — you (or your developer) apply the fixes.
What is llms.txt and do I really need one?
It's a Markdown file at /llms.txt summarizing your site for AI assistants — a convention, not a formal standard, and adoption is voluntary. The audit treats a missing llms.txt as 'needs work,' not a failure. It's cheap to write and helps the assistants that look for it.
Will passing this audit make AI assistants recommend my brand?
Not by itself. This audit fixes the technical layer — crawlers can reach, parse, and quote your pages accurately. Whether assistants *recommend* you is a content and reputation question; pair this with the AI Brand Visibility Monitor for that half.
Can I audit a competitor's site?
Only with the owner's permission. The skill's safety rules require auditing your own site or one whose owner asked you to — and it honors the site's own robots.txt before fetching anything.